Your end-to-end tests pass. Every one of them clicks the Pay button on a 1280px desktop, on a fast connection, with the cookie banner already dismissed in a beforeEach. Meanwhile a real customer on a phone with two bars of signal cannot reach Pay at all, because the cookie banner sits on top of it. Nobody wrote a test for that, because nobody thought of it.
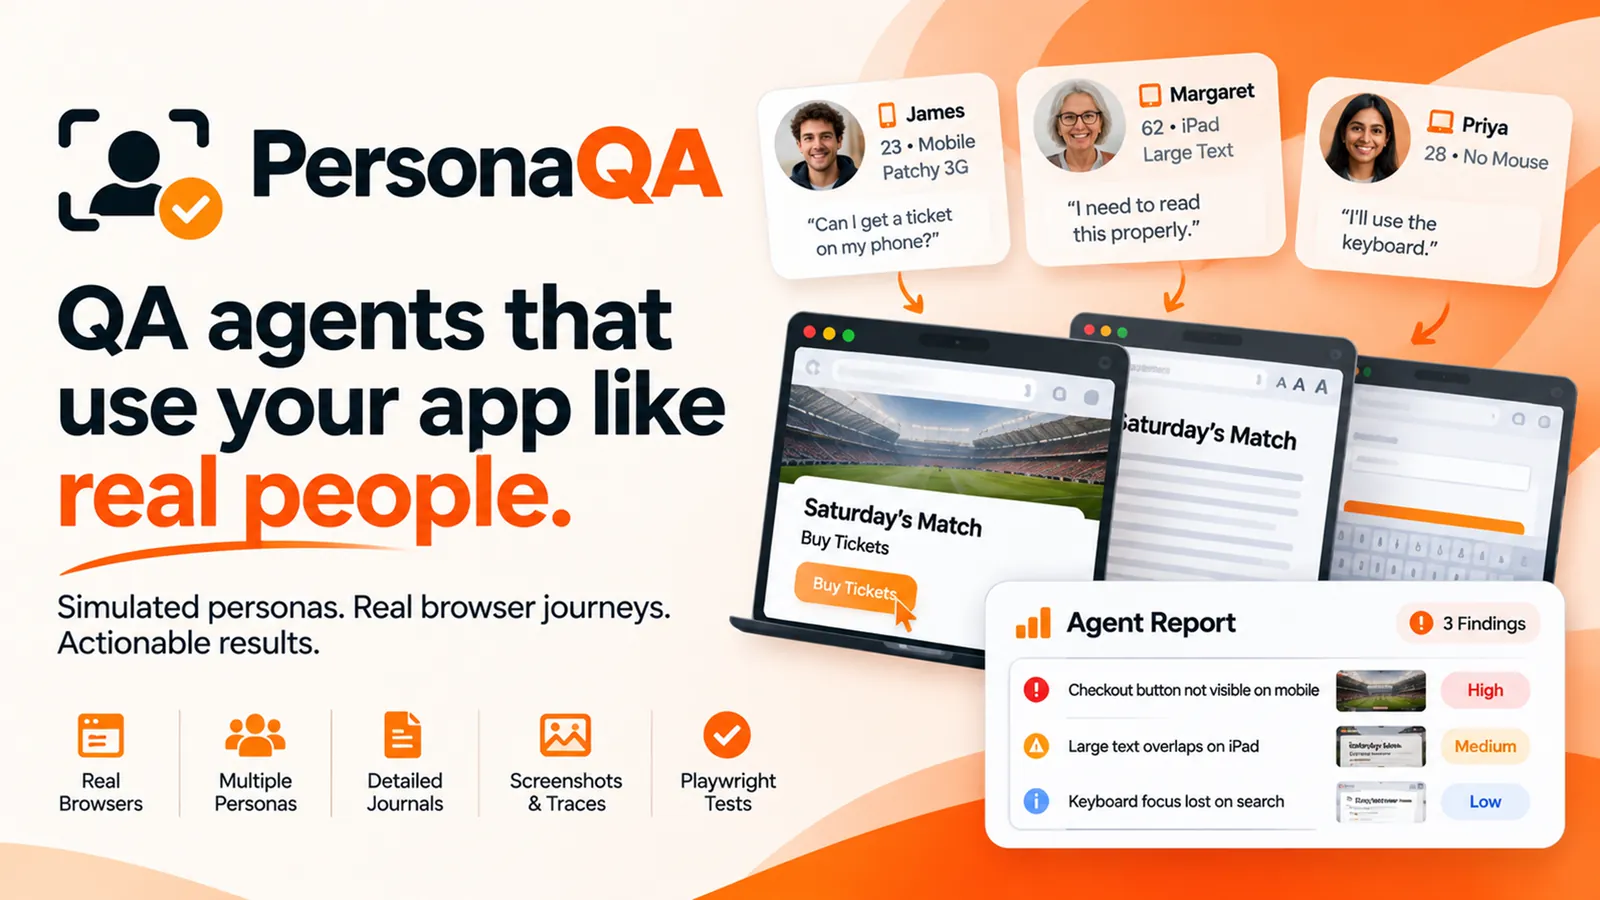
Deterministic tests are brilliant at keeping known behaviour fixed. They are terrible at finding the problems nobody thought of. That is the gap I built PersonaQA to fill: a Claude Code plugin that gives your app a cast of simulated users who drive a real browser as specific people would, then hand back what went wrong in their own words.
A cast, a mission, a real browser
James is 23, on an iPhone with patchy 3G, skims everything and gives up after about eight seconds. Margaret is 71, uses an iPad with text at 150%, reads every word and wants to know exactly what she is paying. Priya never touches a mouse. Tomasz has a Polish locale and English as a second language. Chaos types emoji into every field and double-submits forms.
You give them a mission in plain English and a success rule the server can check:
id: checkout
goal: Buy one adult ticket for Saturday's match and get to the confirmation page.
start_url: /fixtures
time_limit_minutes: 4
success:
  any:
    - url_contains: /order/confirmed
    - text_visible: Order confirmed
data:
  card: "4242 4242 4242 4242"
  expiry: "12/30"
  cvc: "123"
Then one command runs them in parallel:
/personaqa:run james,margaret,priya checkoutEach persona produces a first-person journal, structured issues with screenshots and a Playwright trace. Two inspector agents review the evidence for accessibility and usability, and a coordinator merges everything into a ranked report. Here is Margaret, from a real run against a demo ticket shop:
The card number with spaces was cut off after "4242 4242 4242 4", so I retyped it without spaces. I pressed Pay now and reached "Order confirmed". It said I had paid £29.50, but I had only ever seen £27.00 and no fee or total before paying. I would want to phone someone about that extra £2.50.
That is a hidden fee and a truncating input, found by someone behaving like a real cautious customer, described in a way a product owner understands immediately.
The first prototype lied, convincingly
Before writing any server code, I pointed Claude at the stock Playwright MCP with a persona prompt and sent James through checkout. The journal was believable and useful. It found 7 of the 15 flaws I had planted. And almost everything underneath it was wrong:
- The phone was a narrow window. Only the viewport changed: no touch, no mobile user agent, no throttling, no locale
- James used the address bar. He typed
/checkout?seat=242straight in rather than using the seat map, which no real fan would do - Slowness was invisible. A six second seat map showed up as a tool timeout, not as James waiting and getting annoyed
- One snapshot was 45,600 characters. The seat map has 240 seat links, and that snapshot was re-sent in the history of every later turn
- Success was the model's own claim. The run "succeeded" because the agent said so
- JavaScript was on the table.
browser_evaluatewas there for the taking
The persona prompt was fine. The harness was the problem. Every gap on that list became a feature of PersonaQA's own browser server.
The harness enforces facts, the model plays judgement
That became the design rule for the whole project. Anything that is a fact about the world is decided by code. Anything that is a judgement a person would make is left to the model.
- The server enforces: device, touch, viewport, locale, timezone and text size; CDP network throttling, signal drops and session expiry; mission success, step and time limits; a domain guard; a human action set with no JavaScript and no address bar; typos at the persona's rate
- The model decides: patience, attention, what to tap and type in character, what felt wrong and when to give up
The tool for finishing a session takes a journal and never an outcome. The persona cannot claim success: the server checks the mission's success rules after every action and records the result itself.
Waits are facts, not instructions
Each action is timed until the page settles, with a network tracker that waits for 300ms of quiet and ignores websockets. If the wait exceeds the persona's patience, the server says so as a plain fact: "You waited 9.2s, longer than you would normally put up with (8s)." Whether James gives up is still his call. Enforcing it would make every run identical; reporting it keeps the behaviour human.
A tap lands on whatever is on top
The tap tool presses screen coordinates at the centre of the element, not the element itself. If a cookie banner covers the Pay button, the banner receives the tap, exactly as it would for a finger, and the persona is told "hit the cookie banner instead". The snapshot also flags it up front:
[e14 button "Pay now" covered by "We value your privacy..."]
That is computed in the page with document.elementFromPoint at each control's centre, so even a text-only agent can see an overlay a person would see.
Snapshots a person could have seen
The biggest single lever on both quality and cost is the page snapshot. PersonaQA's snapshot script walks the DOM in the page and returns only what is on screen, with controls inline and refs that stay unique for the whole session. Everything off screen is summarised in a line, so personas scroll as people do. Off-screen refs are refused with "scroll to it first". When the URL has not changed and less than 60% of lines differ, the persona gets a line diff instead of the whole page again.
The seat map that cost 45,600 characters on the stock MCP now costs about 2,000 on a phone and 4,400 on a desktop. Because every later turn re-reads the conversation, that saving compounds through the whole run.
The text view must not see better than a person
The smoke test caught a subtle one. Priya, keyboard only, kept getting further through checkout than she should have. The site had removed every focus outline, yet the snapshot still told her which control had focus. She was seeing better than a sighted keyboard user could. The fix was a check on the focused element's computed outline and box shadow:
[e31 input "Card number" focused, but nothing on screen shows it]With that in place she runs out of steps, writes about losing track of where she was, and the missing focus indicator becomes a finding. It is a good example of the general rule: every shortcut the agent has that a person does not is a bug in the harness.
Deterministic code around model judgement
Models are good at playing people and at deciding whether two issues from different personas are the same problem. They are bad at producing the same ranking twice. So PersonaQA draws a hard line:
- Code: planning and validation (
plan_runloads every persona and mission through the same JSON schemas), success checks, axe-core accessibility scans on every new page state, ranking by severity times personas affected, rendering the report, and scoring - Model: playing personas, the accessibility and UX inspectors' review, and merging duplicate issues into findings
The same applies to measuring the plugin itself. The demo app ships with an answer key the agents never see, and scripts/score.mjs matches findings against it by term groups, not by asking a model. Model comparisons then measure the cast, not the scorer.
Hooks as safety nets
Persona runners are Claude Code subagents with their tools: limited to the browser server, and a PreToolUse hook backs that up by denying anything else when the agent type is the persona runner. A SubagentStop hook sends a runner back once if it started a session but never called finish, so no run ends without a journal. The hooks are Node scripts rather than shell and jq, so they work wherever Claude Code runs.
What it found
I built a small Laravel ticket shop with 15 deliberate flaws: a cookie banner over the Pay button on phones, a card field that truncates spaced numbers, a hidden booking fee, a date picker that traps keyboard focus, sold seats shown only by a paler colour, and so on. One run of the five built-in personas through checkout, with both inspectors and the coordinator:
- 13 of 15 flaws found, 8 of 9 usability and 5 of 6 accessibility
- The two misses were on pages checkout never visits (sign-in and the date filter). Coverage follows missions
- About $1.50 at API rates with Sonnet, measured with Claude Code's
total_cost_usd. On a Pro or Max plan, runs use your plan's allowance instead
Runs are not deterministic, and that is the point for exploration. Never use a persona run as a pass or fail gate. Instead, confirm a finding and turn it into an ordinary test:
/personaqa:report confirm ISSUE-3
/personaqa:test ISSUE-3
The test skill reads the evidence session's action log, which records each target's role and name as the persona saw it, and writes a Playwright spec with getByRole locators that asserts the expected behaviour. It runs once and should fail until the bug is fixed. PersonaQA finds the problems; deterministic tests keep them fixed.
Try it
PersonaQA is framework-agnostic: personas are black-box browser users, so it works on any app you can reach at a URL. It runs in Claude Code and in Cowork sessions on your own computer, and the first session downloads a headless Chromium (about 290 MB) in the background.
/plugin marketplace add phoenix1331/persona-qa
/plugin install personaqa@persona-qa

/personaqa:init https://staging.your-app.test
/personaqa:run james first-visit
Point it at staging, preview or local deploys only: personas fill in forms and pay with test cards. Example GitHub Actions workflows run two or three personas on every pull request with the summary posted as a comment, and the full cast nightly with findings filed as issues.
Summary
Letting a model drive a browser is easy. Making what it finds trustworthy is the work. The lessons that carried PersonaQA from a convincing prototype to useful findings apply to any agent that acts on the world:
- enforce facts in code and leave only judgement to the model
- never let the agent grade its own success
- give the agent exactly the view and the actions a person would have, no more
- keep tool results small and visible-only, because every turn pays for every previous one
- rank, render and score with code so results are repeatable
- turn confirmed findings into deterministic tests rather than gating on agent runs
PersonaQA is on GitHub with a guide covering missions, personas, logins, reports and CI. If you want to see how a cast of personas gets on with your own app, or need a hand building agents you can trust, get in touch via the contact section.