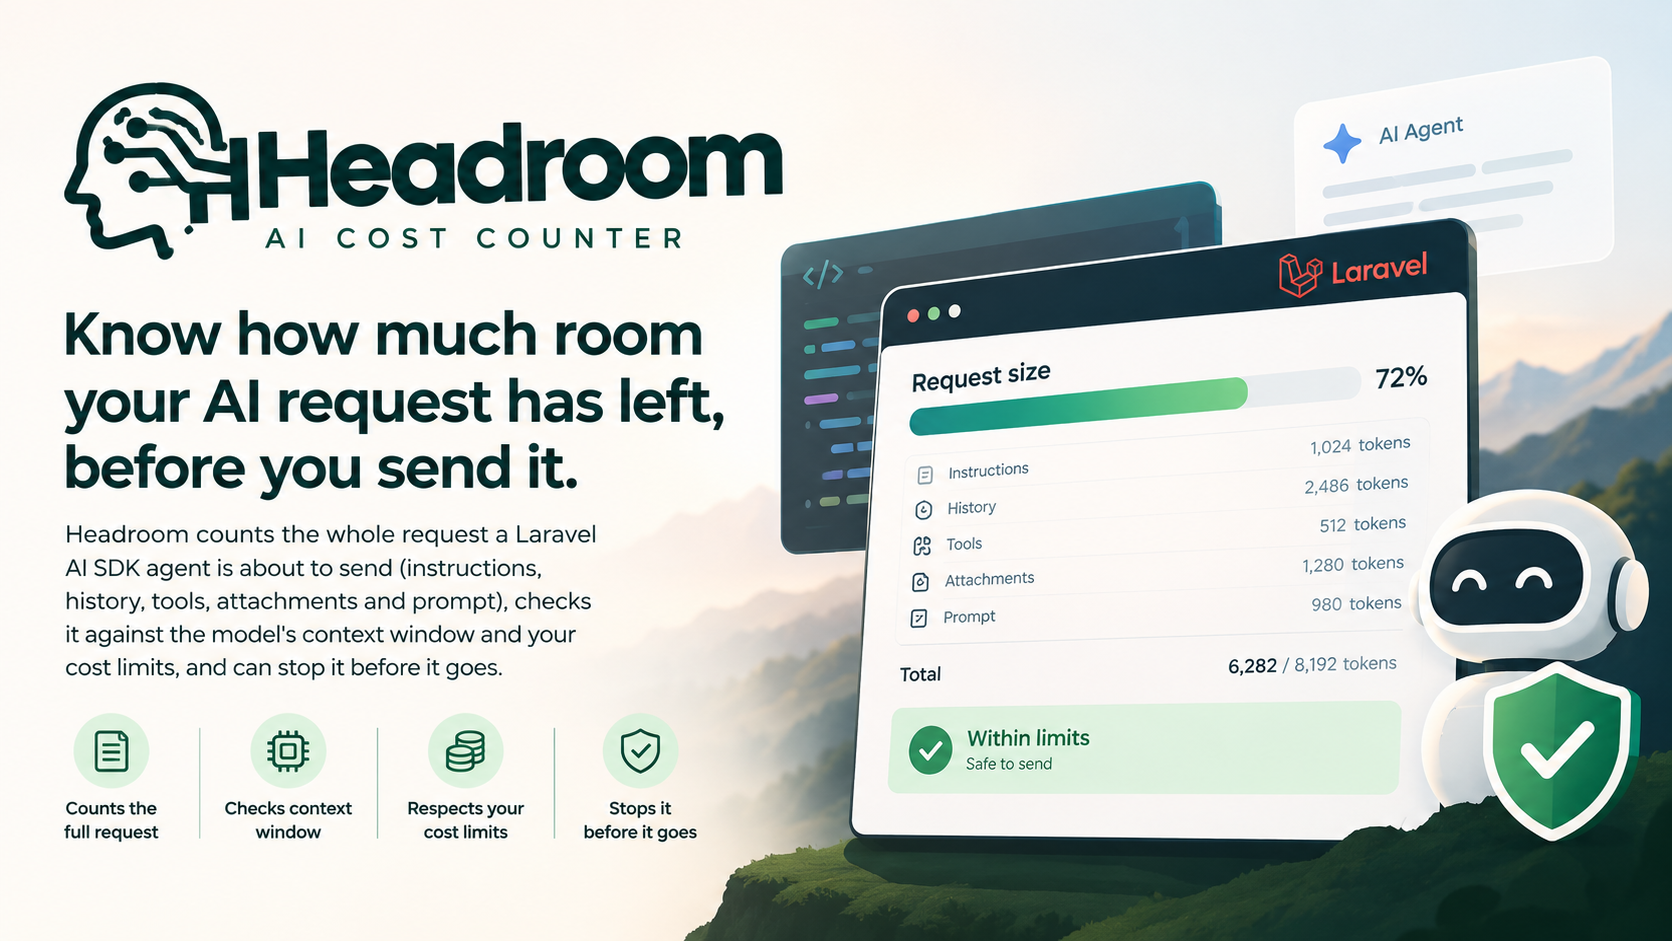
A support chat works perfectly in testing. Three weeks after launch, one customer's conversation has grown to two hundred messages, the agent pulls in a dozen retrieved documents per reply, and the request quietly goes past the model's context window. The provider rejects it, or worse, the oldest history is dropped and the agent forgets the refund it agreed to an hour ago. The same growth shows up on the invoice, usually driven by a handful of tenants nobody was watching.
The Laravel AI SDK does not tell you how big a request is before you send it. Token counting was proposed for core in laravel/ai#704 and declined, which is a reasonable call for the SDK, but it leaves the problem with you. I built Headroom to answer one question: how much room does this request have left, before it goes?
Why counting strings is not enough
There are PHP tokenisers already. They count a string you hand them, usually with OpenAI's encoding. That works for a single prompt, but an agent request is not a string. By the time the SDK calls the provider, it has assembled:
- the agent's instructions
- the conversation history, including tool calls and tool results from earlier steps
- every tool's JSON schema, which can easily outweigh the prompt
- a structured output schema, if the agent has one
- attachments
- the user's prompt, often the smallest part
If you rebuild that by hand to count it, you are guessing at what the SDK will do, and the guess drifts every time the SDK changes how it settles abandoned tool calls or filters provider-specific tools. Headroom counts the request the SDK would actually build, so the number matches what goes over the wire.
Counting an agent request
The entry point takes the same arguments as $agent->prompt():
use Phoenix1331\AiHeadroom\Facades\Headroom;

$count = Headroom::for(new SupportAgent($user), 'Where is my refund?');

$count->total();          // 171297
$count->breakdown();      // ['instructions' => 1812, 'history' => 162240, 'tools' => 3604, 'attachments' => 0, 'prompt' => 14]
$count->percentUsed();    // 17.13
$count->remaining();      // tokens left, negative when it overflows
$count->fits();           // true
$count->estimatedCost();  // input plus worst-case output, in USD or GBP
The breakdown is where the value usually is. In that example the prompt is 14 tokens and the history is 162,240. You do not need a bigger model, you need to summarise the conversation. You can see the same picture from the terminal without writing code:
php artisan headroom:inspect "App\Ai\Agents\SupportAgent" "Where is my refund?"
It prints the breakdown with each section's share, the context usage and the estimated cost, and exits with 1 when the request does not fit, so it works as a CI check too.
Rebuilding the request without sending it
Headroom::for() has to produce the same request the SDK would, without calling the model. The obvious shortcut, faking the agent and capturing the request, mutates global state and writes conversations, so that was out. Instead a RequestResolver mirrors the SDK's own steps from public data: provider and model resolution (including #[UseCheapestModel] style attributes), history, tool resolution, and the clean-up the agent loop runs before the first step.
Mirroring code is only safe if something proves it still matches. A parity test runs a set of fixture agents through the real SDK, captures the request it actually builds, and requires an identical fingerprint from the resolver. I mutation-checked it: skipping the tool-call settling or the tool filtering each fail the test. A weekly CI job installs the newest laravel/ai release, ignoring the version constraint, so SDK drift shows up as a red build on a Monday morning rather than a wrong count in production.
Guarding every step with middleware
Counting on demand is useful. Stopping a request automatically is the point. laravel/ai v1.2 hands agent middleware the fully resolved PendingStep, which is exactly what is about to be sent, so the guard needs no reflection into SDK internals:
use Phoenix1331\AiHeadroom\Middleware\EnsureHeadroom;

class SupportAgent implements Agent
{
    use Promptable;

    public function middleware(): array
    {
        return [new EnsureHeadroom(maxPercentOfContext: 80, maxCost: 0.20)];
    }
}
This runs on every step of an agent run, not just the first. That matters for tool loops: each tool result is appended to the history, so step four can be far larger than step one. Each step is checked against the context window, then the percentage limit, then the cost limit. Over a limit, Headroom fires RequestBlocked and throws TokenLimitExceeded, which carries the full count so you can decide what to do:
use Phoenix1331\AiHeadroom\Enums\LimitType;
use Phoenix1331\AiHeadroom\Exceptions\TokenLimitExceeded;

try {
    $response = (new SupportAgent($user))->prompt($message);
} catch (TokenLimitExceeded $e) {
    if ($e->limit === LimitType::Cost) {
        return back()->withErrors('This request is too expensive to run.');
    }

    $conversation->summariseOlderMessages();

    $response = (new SupportAgent($user))->prompt($message);
}
If blocking is too aggressive while you learn your traffic, (new EnsureHeadroom(...))->report() fires HeadroomLow instead and lets the request through.
Exact counts, estimates, and when to pay for which
Anthropic, OpenAI and Gemini each have a token counting endpoint. Those give exact numbers, but every call is a network round trip and sends your prompt to the provider. A local estimate is free and private, but only OpenAI models share the o200k tokeniser Headroom uses locally. Everyone else is an approximation.
The default auto mode splits the difference. It estimates locally first. A request that clearly fits, or clearly does not, never waits for the network. Only a request whose estimate lands within 15% of a limit escalates to a native count. Accuracy is spent where a decision is actually being made.
Reusing the SDK's own serialisation
A native count is only exact if the body sent to the counting endpoint matches the body the SDK would send to generate. Rather than rebuild that payload, the counters subclass the SDK's Anthropic and OpenAI gateways, take the request body they produce, and strip it down to the fields the counting endpoint accepts. Gemini is the exception: the SDK uses Gemini's Interactions API, which countTokens does not accept, so Headroom maps that request to a generateContentRequest itself.
Self-calibration
After every step the middleware fires TokensUsed with what the provider actually reported. Headroom compares that with its estimate and learns a correction factor per model, as a weighted running average with each observation clamped so one odd request cannot skew it. Once a model has enough samples, estimates are multiplied by that factor, and the safety margin added on top shrinks from 10% towards a 2% floor as the measured error drops. The count reports its own confidence, so "how accurate is it?" becomes a number your app has measured rather than one I have promised.
How accurate is the estimate, honestly?
The repository ships an accuracy suite that sends a deliberately mixed corpus to each provider's counting endpoint and compares it with the local estimate. Against Gemini 3.8 Flash, the most recent run looked like this:
Sample       Native  Estimate  Error
prose           157       176  +12.1%
code            266       258   -3.0%
json            293       264   -9.9%
french          149       161   +8.1%
japanese        127       180  +41.7%
tool-heavy      555       515   -7.2%

Mean absolute error: 13.7%
A few things are worth reading out of that:
- Over-counting is the safe direction. The Japanese sample is the worst number, but over-counting only means a limit trips early or a cost estimate runs high. It never lets an oversized request through.
- Under-counting is the real risk. Code, JSON and tool-heavy prompts come in up to about 10% low, which the default 10% safety margin only just covers. If you run close to a hard limit with that kind of content, use
autoornative. - Calibration needs uniform traffic. Across six wildly different samples, a single correction factor cannot fit them all, and the leave-one-out calibrated error was slightly worse at 15.4%. A real app's traffic is far more uniform than this corpus, which is the situation calibration is built for.
I would rather publish that table than a single flattering percentage. The full report is regenerated by composer test:accuracy and lives in the repository.
Events, privacy and testing
Headroom stores nothing about your requests. It fires TokensCounted, TokensUsed, HeadroomLow, RequestBlocked and RequestFailed, linked by a request ID and the SDK's invocation ID, and you decide whether to log them, chart them or ship them to a dashboard. No event contains prompt, response or provider error text, so a listener cannot accidentally write customer messages into your logs. You can tag requests with your own scalar context, such as a tenant ID, which is how you find the handful of tenants driving the bill.
If prompt content must never leave your app for counting, HEADROOM_METHOD=estimate keeps everything local.
For your own test suite, the fake replaces only the counting. Middleware, limits and listeners still run for real:
Headroom::fake([SupportAgent::class => 900_000, 'claude-*' => 1_200]);

expect(fn () => (new SupportAgent($user))->prompt('Hello'))
    ->toThrow(TokenLimitExceeded::class);

Headroom::assertCounted(SupportAgent::class);
Summary
Context windows and AI bills both fail quietly. Nothing in the request path tells you a conversation has grown past what the model can hold, or that one tenant is costing ten times the rest. Headroom puts a number on every request before it is sent:
- it counts the whole agent request the SDK would build, not a string you assembled
- it guards every step of an agent run through middleware, including tool loops
- it uses exact provider counts only where a decision is close, and estimates everywhere else
- it learns its own accuracy from your traffic and reports it
- it fires events with figures only, so you can record usage without storing prompts
Install it with composer require phoenix1331/laravel-ai-headroom. It uses the provider credentials you already configured for laravel/ai, so there is nothing else to set up. The source, accuracy report and events reference are on GitHub. If you are running agents in production and want a second pair of eyes on cost or context handling, get in touch via the contact section.